# GSoC 2026 | Daemon that corrects out-of-sync cover art and event art metadata on archive.org
**URL:** https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396
**Category:** MusicBrainz
**Tags:** cover-art-archive, gsoc
**Created:** [March 12, 2026, 4:51pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396 "2026-03-12T16:51:38Z")
**Posts on this page:** 8
**Page:** 1
### Author:  [@minus\_1](https://community.metabrainz.org/u/minus_1)
#### Post date: [March 12, 2026, 4:51pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/1 "2026-03-12T16:51:38Z")
# **Contact Information**
Name:
Email:
Matrix handle: @minus-1:matrix.org
LeetCode: [https://leetcode.com/u/minus-1](https://leetcode.com/u/minus-1)
Github: [https://github.com/MinusOne-01](https://github.com/MinusOne-01)
LinkedIn:
Mentor: @Bitmap
Co-mentors: @reosarevok @yvanzo
Timezone:
Languages: English
# **Introduction**
I am minus1, a programmer with a strong interest in backend systems and database driven development. Over the past several months, I have been building projects that involve designing systems around async processing, background workers and relational database modelling.
One of them is a Job Queue system that models full job lifecycles (pending, processing, completed, failed, dead) and implements reliability mechanisms such as retry handling and failure recovery logic. Also storing job state and execution history to enable lifecycle tracing and failure diagnostics.
Github repo - [GitHub - mns-one/job-queue-system · GitHub](https://github.com/MinusOne-01/job-queue-system)
You can also find my other projects in Python, Full stack development and Backend systems in the Programming Precedents section.
The Artwork-Indexer project closely aligns with what I have been learning and building. My projects taught me to think carefully about how background processes behave under failure conditions and how data consistency is maintained over time which is exactly the knowledge needed to understand the current architecture of Artwork-Indexer and extend it with new functionality.
Since deciding to apply, I have been actively exploring the MusicBrainz and Artwork\_Indexer codebase to understand their architecture and schema design. During that I also engaged with the community and mentor to discuss open issues which helped me to contribute through PRs:
- [MBS-13545](https://github.com/metabrainz/musicbrainz-server/pull/3737) - Included cover art related data in Sample dump
- [IMG-163](https://github.com/metabrainz/artwork-indexer/pull/7) - Updated reload function to use custom config file path
# **Current Architecture of Artwork-Indexer**
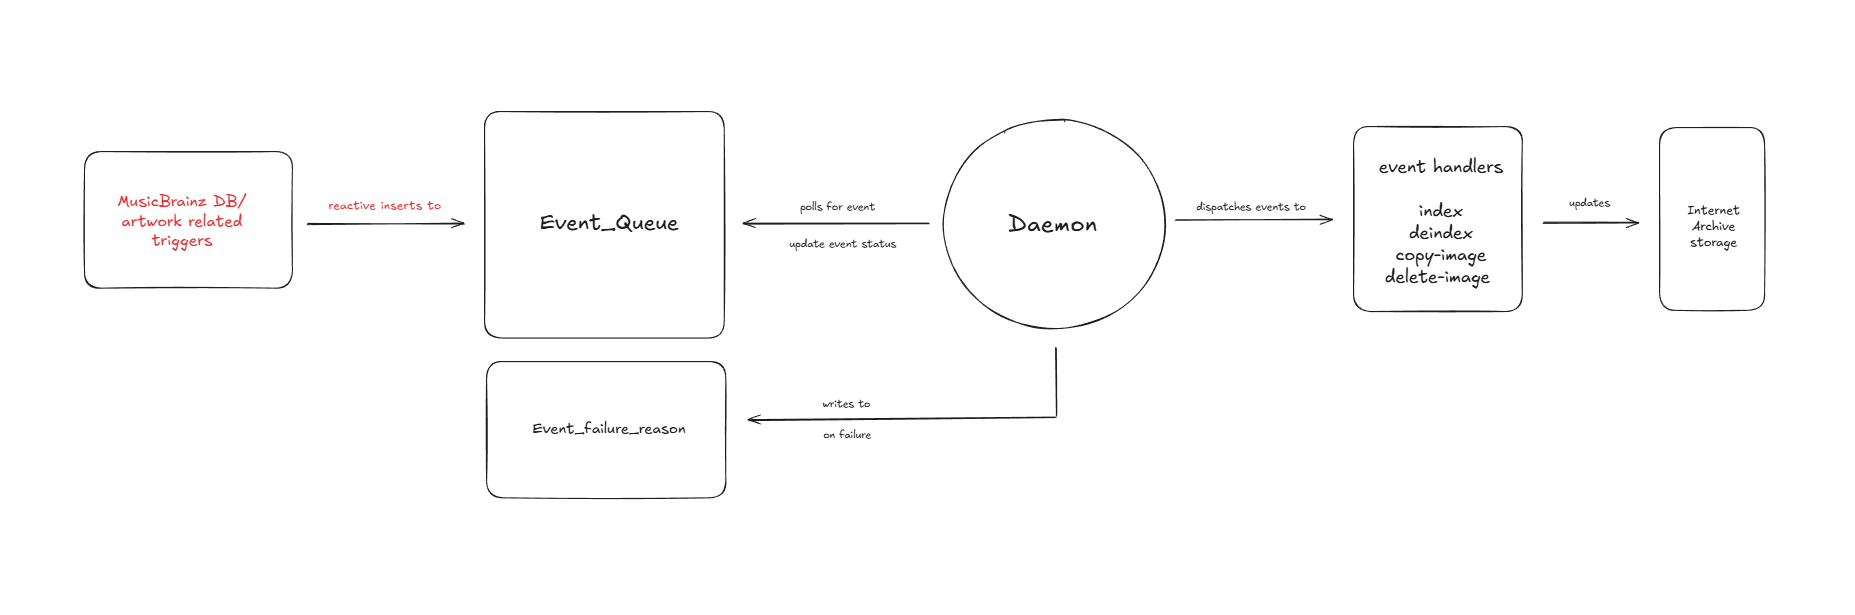
Artwork-indexer is a database-driven daemon that processes the events from Event\_Queue. These events are generated by PostgreSQL when relevant MusicBrainz/CAA/EAA data changes.
Right now, events are only added reactively upon new changes to database so it cannot detect or repair historical drift between MusicBrainz and Internet Archive data.
## Current flow of daemon event loop:
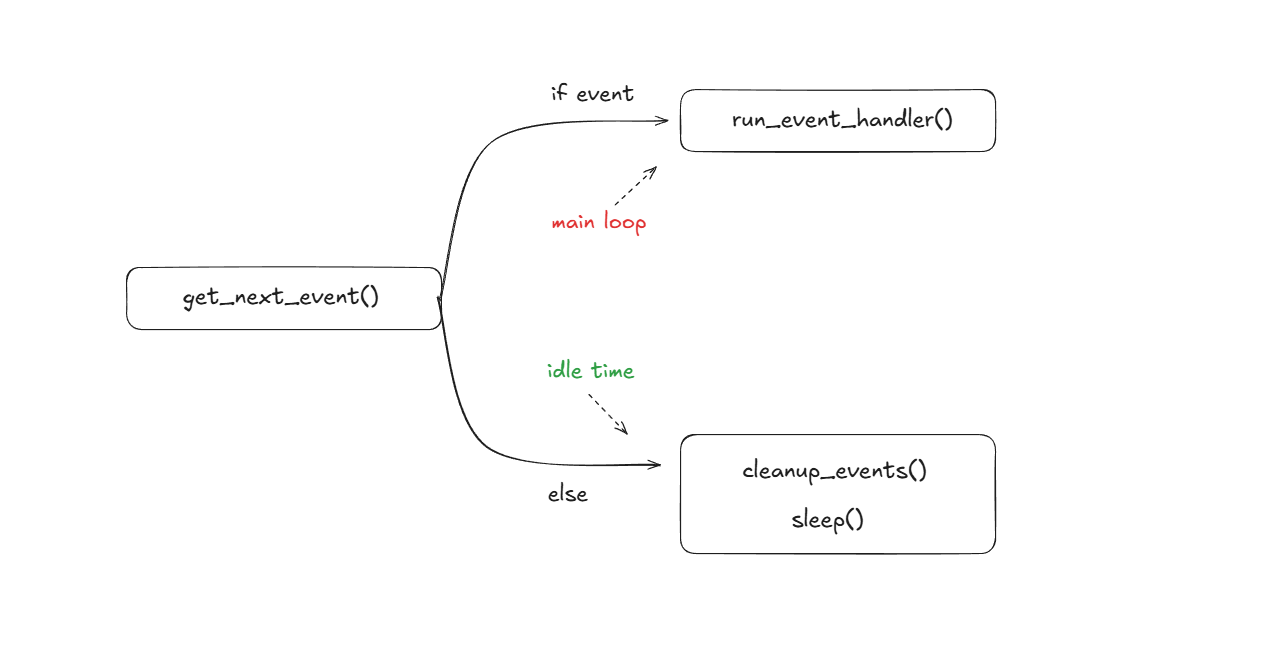
1. Polls the event\_queue for any available event to process via get\_next\_event()
2. If event is available, dispatch it to correct handler via run\_event\_handler()
3. If no event is available, periodically run cleanup\_events()
4. Then sleep with backoff and poll again
# **Proposed change**
Within the existing daemon loop, add a secondary Audit loop that runs on idle time to audit entities and decide whether they can be repaired using the existing repair loop or need manual review.
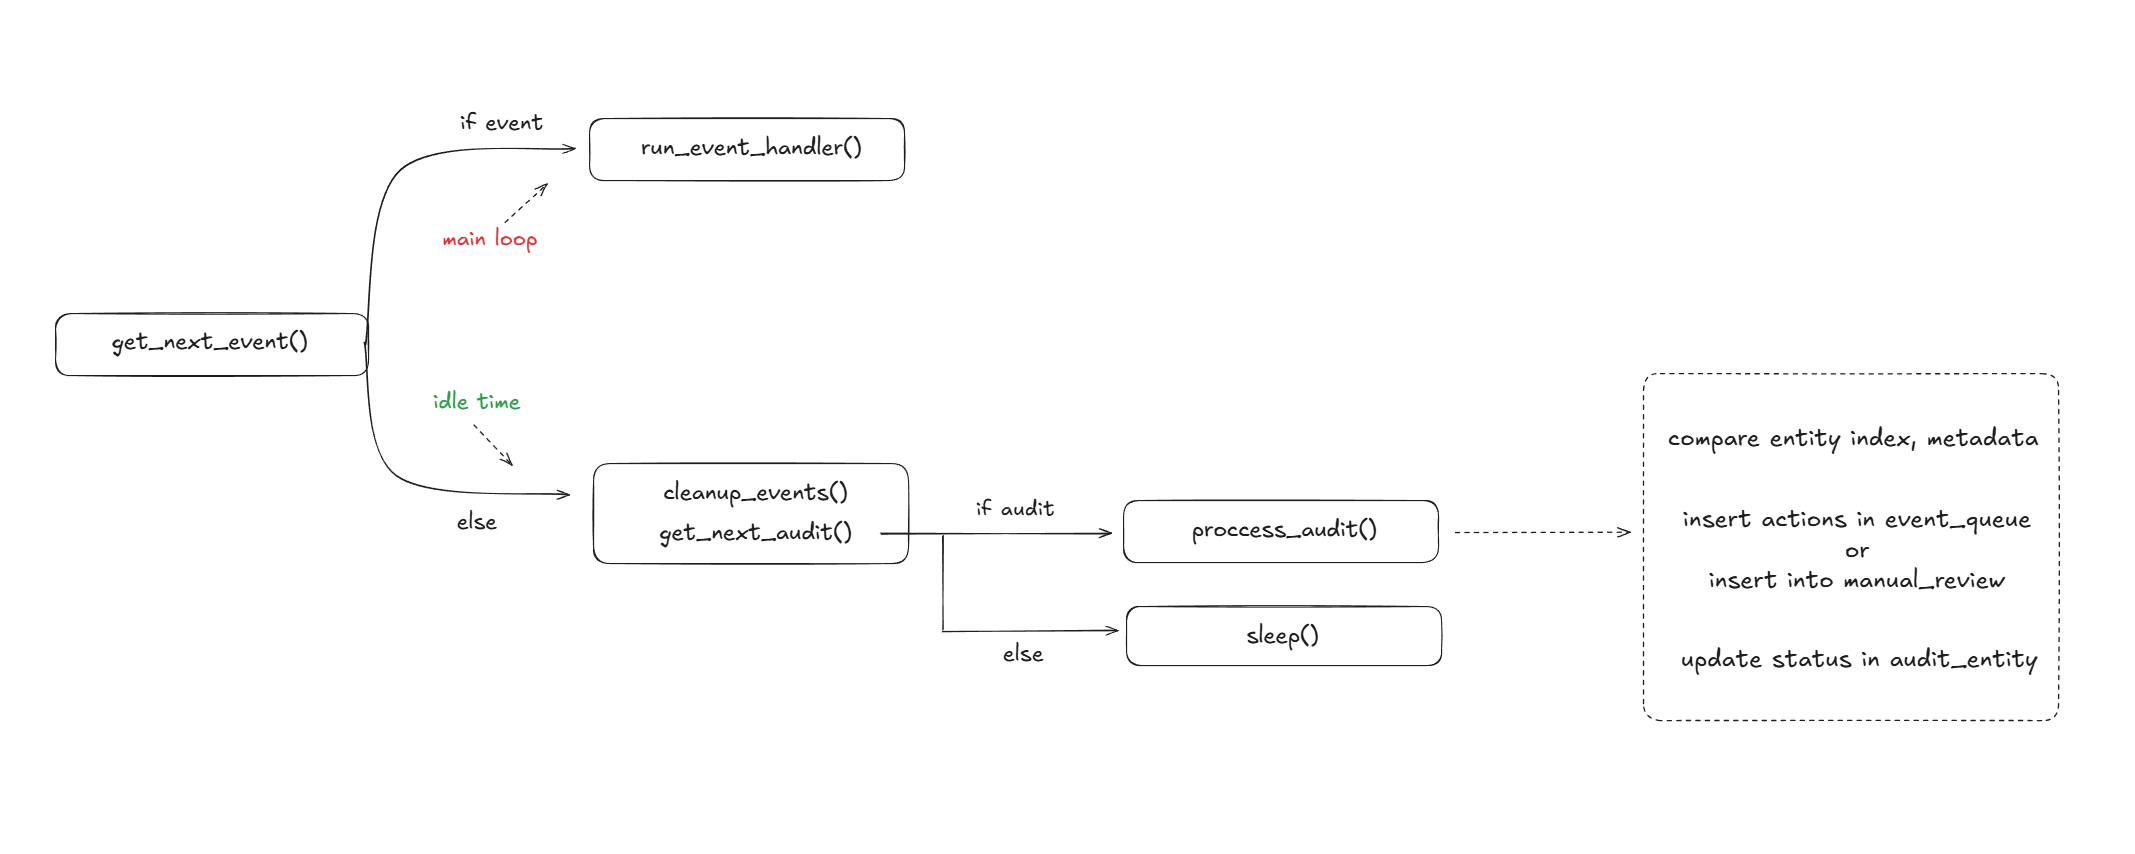
Initially the number of entities to audit will be quite high so in order to not hammer the IA with constant daemon execution, we can add a limit to audit X entities per hour or per day as necessary.
The Audit\_Entity row will be selected using FOR UPDATE SKIP LOCKED and status will be changed to ‘audit\_in\_progress’ to avoid other instances claiming the same row.
Updated flow in Idle time when no event is available,
1. periodically run cleanup\_events()
2. run get\_next\_audit() with guardrails/limit
3. if entity available for audit, update status ‘audit\_in\_progress’ and run process\_audit()
4. else sleep with backoff and poll again
# **Schema**
To track which entities are available for audit and persisting their audit results, 2 new tables will be added to the current schema.
# **Audit\_Entity table**
### **Structure:**
```
CREATE TABLE artwork_indexer.audit_entity (
id BIGSERIAL PRIMARY KEY,
entity_type artwork_indexer.indexable_entity_type NOT NULL,
gid UUID NOT NULL,
status artwork_indexer.audit_entity_status NOT NULL DEFAULT 'unchecked',
priority SMALLINT NOT NULL DEFAULT 100 CHECK (priority >= 0),
last_audit_at TIMESTAMPTZ NULL,
UNIQUE (entity_type, gid)
);
```
### **Use of column(s):**
**entity\_type, gid** will uniquely identify which entities exist under Audit tracking.
**status** will have these states for each entity:
```
CREATE TYPE artwork_indexer.audit_entity_status AS ENUM (
'unchecked', -- new entity that needs audit
'audit_in_progress', -- currently being audited
'clean', -- no issues found during audit
'manual_review', -- issues found that require manual review
'repair_queue', -- actions were enqueued in event_queue for repair
'legacy' -- entities deleted/merged and no longer exist in MB
);
```
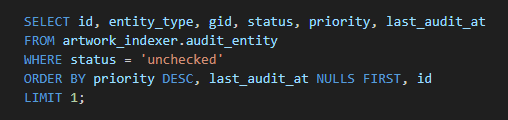
**status, priority, last\_audit\_at** will be used to determine which entity needs to be audited next, example query:
```
SELECT id, entity_type, gid, status, priority, last_audit_at
FROM artwork_indexer.audit_entity
WHERE status = 'unchecked'
ORDER BY priority DESC, last_audit_at NULLS FIRST, id
LIMIT 1;
```
### **Indexing:**
**entity\_type, gid** - via UNIQUE constraint
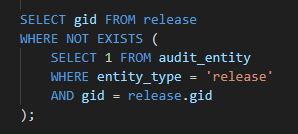
Used for lookups to get entities that does not exist in Audit\_Entity.
Example query:
```
SELECT gid FROM release
WHERE NOT EXISTS (
SELECT 1 FROM audit_entity
WHERE entity_type = 'release'
AND gid = release.gid
);
```
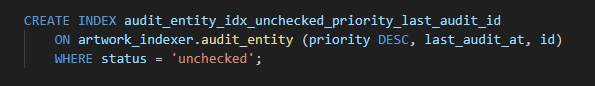
**priority, last\_audit\_at, id**
Used for getting next entity to audit:
```
CREATE INDEX audit_entity_idx_unchecked_priority_last_audit_id
ON artwork_indexer.audit_entity (priority DESC, last_audit_at, id)
WHERE status = 'unchecked';
```
# **needs\_manual\_review table**
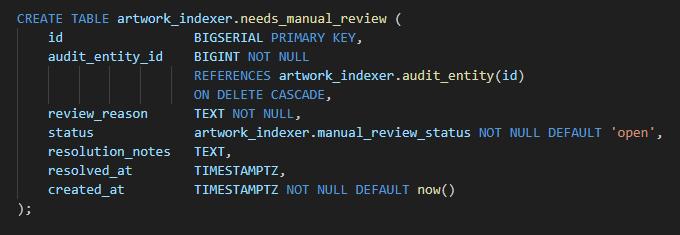
### **Structure:**
```
CREATE TABLE artwork_indexer.needs_manual_review (
id BIGSERIAL PRIMARY KEY,
audit_entity_id BIGINT NOT NULL
REFERENCES artwork_indexer.audit_entity(id)
ON DELETE CASCADE,
review_reason TEXT NOT NULL,
status artwork_indexer.manual_review_status NOT NULL DEFAULT 'open',
resolution_notes TEXT,
resolved_at TIMESTAMPTZ,
created_at TIMESTAMPTZ NOT NULL DEFAULT now()
);
```
### **Use of column(s):**
**audit\_entity\_id** - links review record to audited entity in Audit\_Entity
**review\_reason** - defines why a manual intervention is needed
**status** will have these states:
```
CREATE TYPE artwork_indexer.manual_review_status AS ENUM (
'open', -- needs manual review
'resolved', -- review completed and issue resolved
'wont_fix' -- review completed but could not be fixed
);
```
**resolution\_notes** - description for what was actions were taken
**resolved\_at** - timestamp when review was closed
**created\_at** - timestamp when entry was created
### **Indexing:**
Partial index on **audit\_entity\_id** to check for open issues:
```
CREATE UNIQUE INDEX needs_manual_review_open_uniq
ON artwork_indexer.needs_manual_review (audit_entity_id)
WHERE status = 'open';
```
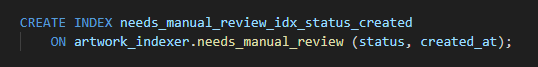
**status, created\_at** for quick issue listing:
```
CREATE INDEX needs_manual_review_idx_status_created
ON artwork_indexer.needs_manual_review (status, created_at);
```
# **Seeding entities into Audit\_Entity**
## **Fresh data using existing event loop**
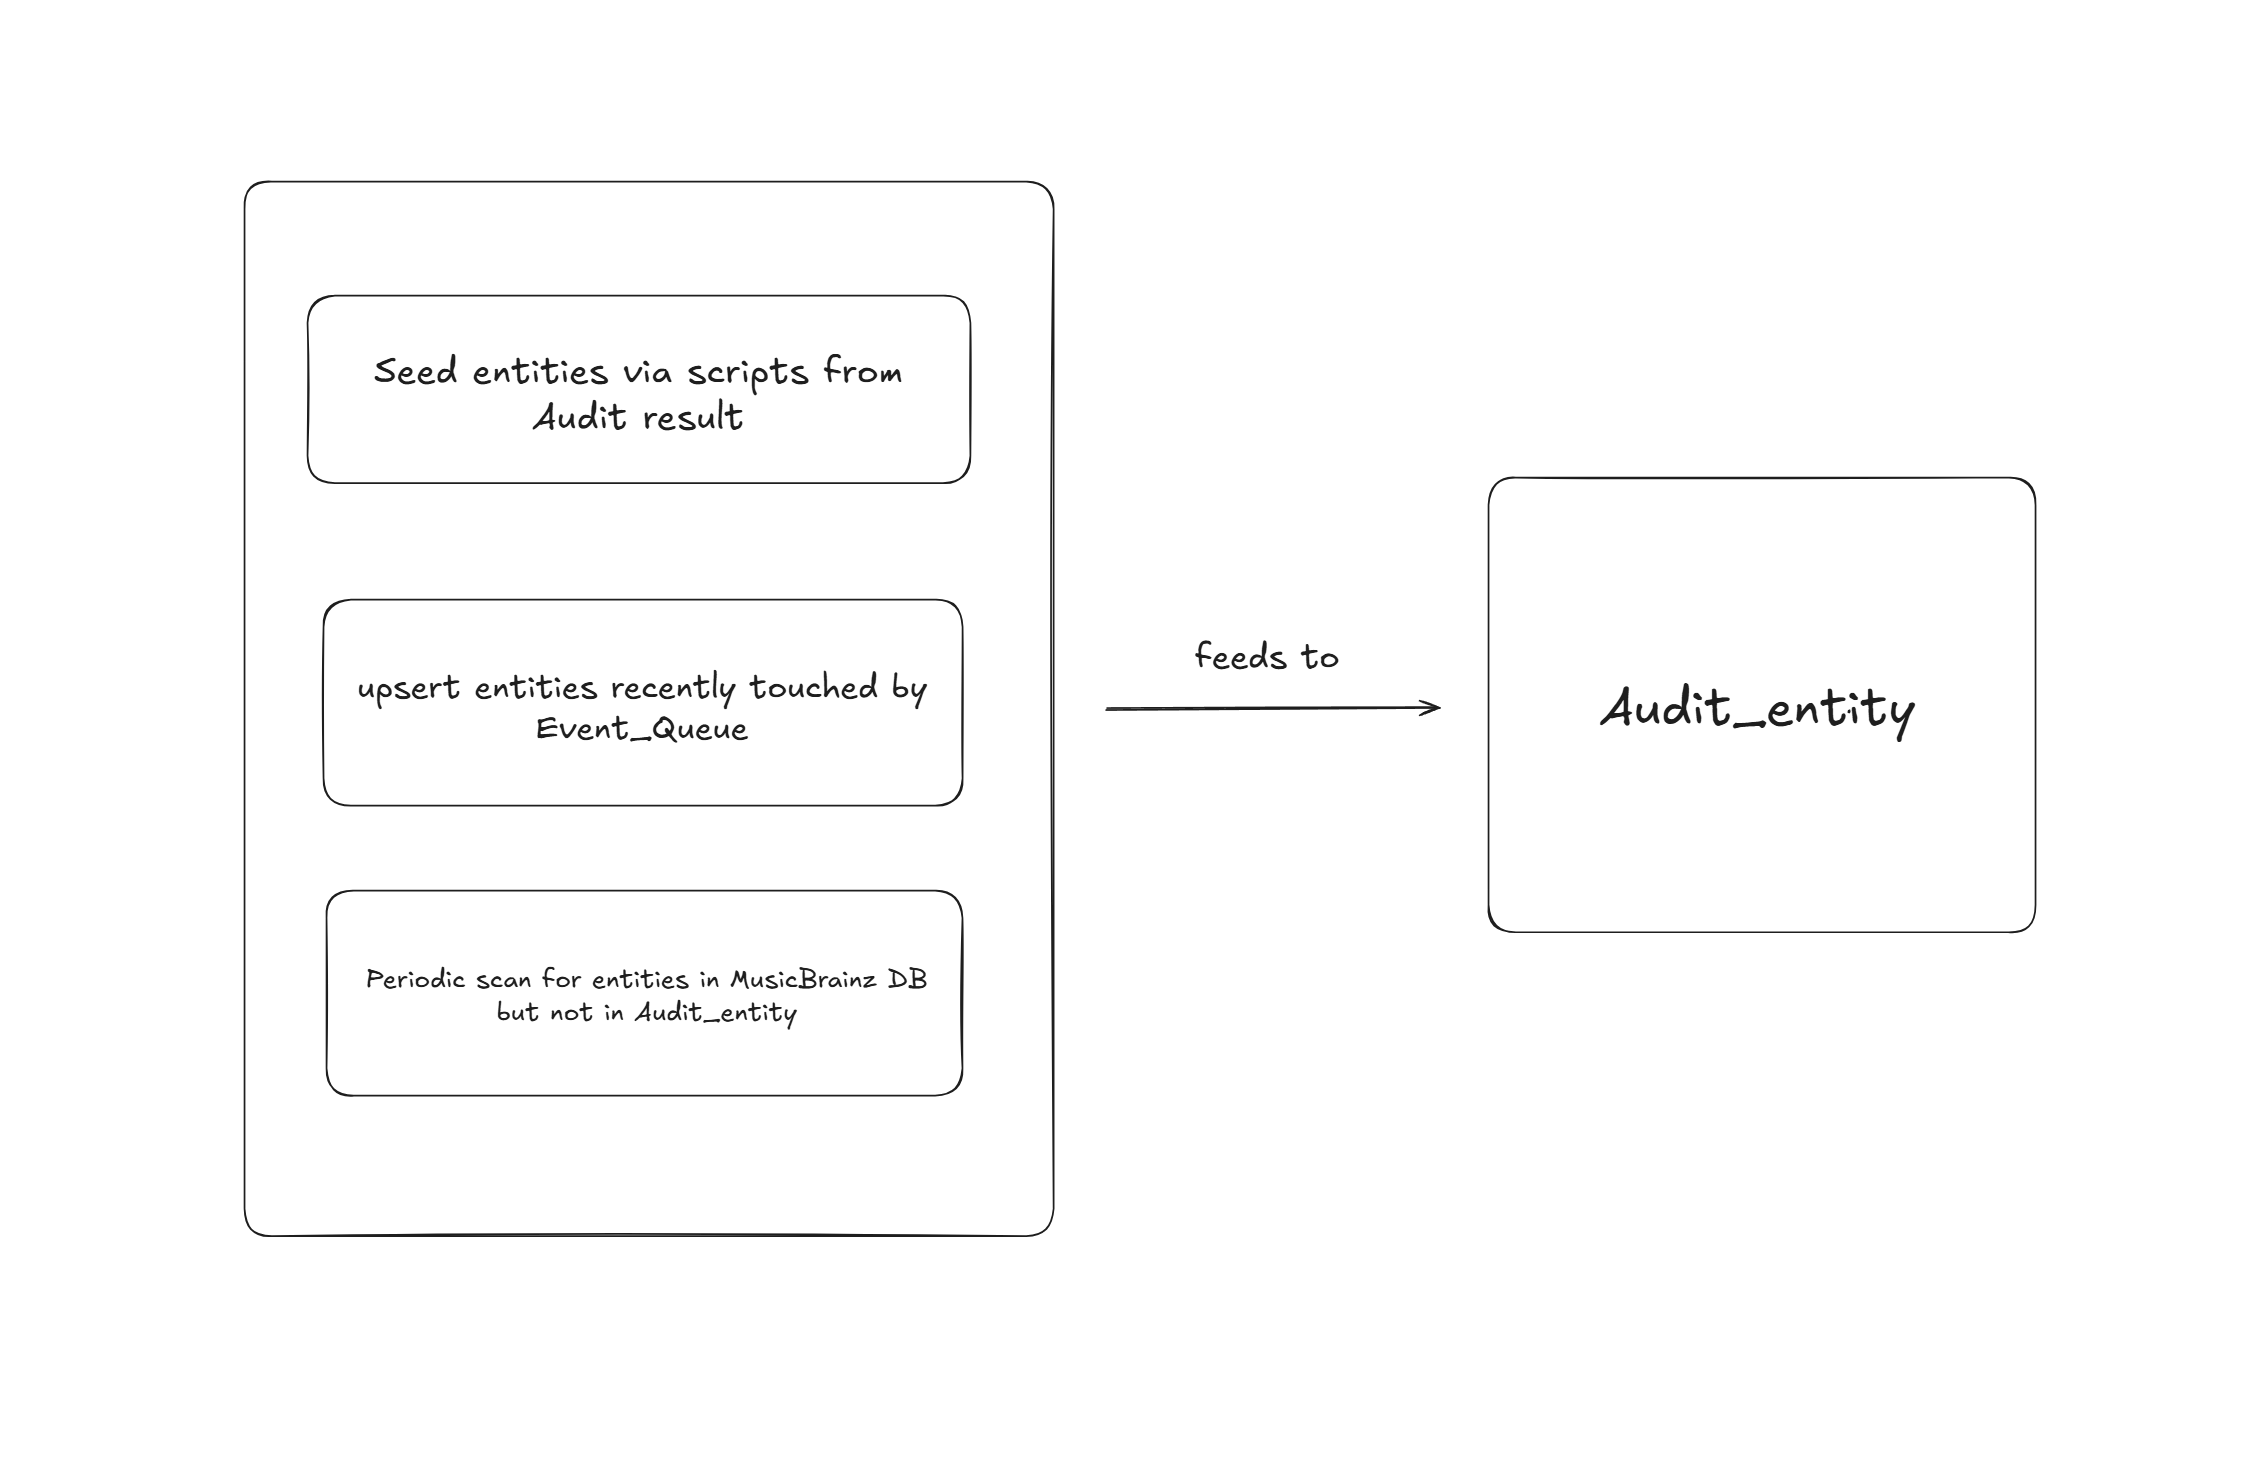
The current event loop already reacts to any change in the CAA/EAA database. Upon completion or failure of an event in event\_queue, we can upsert the associated entity into Audit\_Entity (if missing) and update the status accordingly.
That way using the existing loop Audit\_Entity will have the latest status for each entity and any new entity previously not there will be inserted.
## **IMG-129 Audit results**
Auditing data of IMG-129 have well organised results in structured format. A lot of entities in them might not exist in MusicBrainz DB anymore so we can use them to check if any orphaned files still exist on IA.
Since this Audit data is quite old now, it should not be directly inserted into event\_queue. First the available entities need to be fetched, normalized and inserted into the Audit\_Entity table so fresh decisions can be made for those entities.
## **MusicBrainz Database**
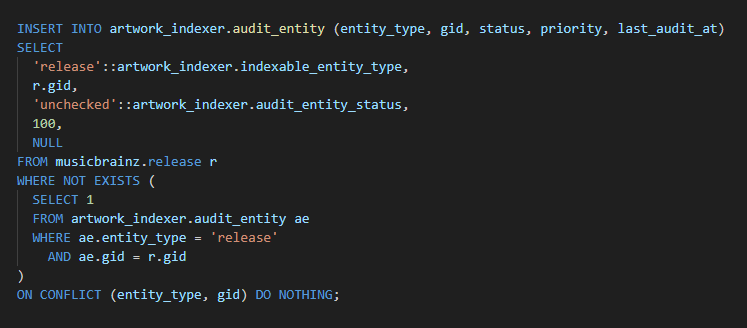
Scripts will be used to backfill entities not in Audit\_Entity from the MusicBrainz database.
Example:
```
INSERT INTO artwork_indexer.audit_entity (entity_type, gid, status, priority, last_audit_at)
SELECT
'release'::artwork_indexer.indexable_entity_type,
r.gid,
'unchecked'::artwork_indexer.audit_entity_status,
100,
NULL
FROM musicbrainz.release r
WHERE NOT EXISTS (
SELECT 1
FROM artwork_indexer.audit_entity ae
WHERE ae.entity_type = 'release'
AND ae.gid = r.gid
)
ON CONFLICT (entity_type, gid) DO NOTHING;
```
## **Orphaned Items from IA**
Scripts will be used to scan the IA CAA and EAA collections via the IA Search API, extract gid from each IA item identifier and upsert that gid into Audit\_Entity to get all orphaned/legacy items.
# **Audit process for each entity**
Currently MusicBrainz uses 2 files to provide necessary information about an Entity (Release/Event) to Internet Archive,
- mb\_metadata.xml
- index.json
### **mb\_metadata.xml**
This file contains all the text based info like:
- title, status, language
- credited artist info - name, sort\_name, country
- release event info
- barcode
- asin
- boolean info about cover art availability
- event name
- event setlist
- supporting artist details
### **index.json**
This file provides the details about all available binaries (artworks) for an Entity.
Currently the Artwork-Indexerer uses **fetch\_image\_rows()** to get all cover\_art rows for an Entity, then **build\_image\_json()** converts the info from that row into an object.
That way, all artwork objects under an Entity are packaged together into a json file that is sent to IA as index.json.
These 2 files will be used for the Audit process flow:
- Build States
- Compare
- Decision handling
# **Build states**
## **Expected State**
This is the Source of truth from the MusicBrainz database.
The json file is already generated by Artwork-Indexer for CAA/EAA so those functions/logic can be reused to build that file.
The xml file will be fetched from mb web server using these endpoints,
Release - [https://musicbrainz.org/ws/2/release/{mbid}?inc=artists](https://musicbrainz.org/ws/2/release/%7Bmbid%7D?inc=artists)
Event - [https://musicbrainz.org/ws/2/event/{mbid}?inc=artist-rels+place-rels](https://musicbrainz.org/ws/2/event/%7Bmbid%7D?inc=artist-rels+place-rels)
## **Actual State**
Entity files and metadata fetched from the Internet Archive server.
IA provides this endpoint to get metadata of an Entity,
[https://archive.org/metadata/mbid-](https://archive.org/metadata/mbid-)
It includes entity metadata and list all available files for entity like:
- index.json
- mb\_metadata.xml ( metadata from MB side )
- meta.xml ( metadata from IA side )
- original artwork
- derived files such as thumbnails, metadata log
Then mb\_metadata.xml and index.json can be fetched using these endpoints,
[https://archive.org/download/mbid-{mbid}/index.json](https://archive.org/download/mbid-%7Bmbid%7D/index.json)
[https://archive.org/download/mbid-{mbid}/mbid-{mbid}\_mb\_metadata.xml](https://archive.org/download/mbid-%7Bmbid%7D/mbid-%7Bmbid%7D_mb_metadata.xml)
# **Compare**
Both State files will be compared by:
- Does this entity exist on MB DB?
- Does IA have the necessary files?
- Field and values in xml and json file
- Types used by values like string, int
- Ordering of images in index.json
# **Decision Handling**
Multiple checks will run in sequence and a flag method will be used to determine the final decision. So if the manual\_review flag is set at any point then no event\_queue actions will be inserted.
Also if an entity needs more than one action then execution order will be taken into account like if both delete\_image and index action is required then index will be dependent on delete\_image.
Overview of checks,
## **Entity only exists on IA ( Orphaned entities )**
- if IA file listing has index.json or main image,
- any other leftover file like log, xml, thumbnails,
## **Entity exists on MB Database**
- if mb\_metadata.xml or index.json is missing on IA,
- if mb\_metadata.xml on IA has mismatch in fields or values,
- Also the meta.xml file contains metadata fields like collection, noindex, mediatype. If these are missing or incorrect then index action as these fields are sent via the http headers in index handler function.
- if index.json on IA has extra images,
- if index.json on IA side has:
# **Timeline**
## **Community bonding period ( May 1 to May 26 )**
- Trace the Artwork-Indexer execution flow end to end, discuss any remaining doubts with mentor
## **Week 1**
- Finalize and implement the structure for Audit\_Entity and needs\_manual\_review table
## **Week 2**
- Draft Implementation details, execution flow, retry and backoff mechanisms for the Audit process
- Draft functions to build index.json and fetch xml files
- Draft decision handler logic to compare states
## **Week 3**
- Test Audit process flow, execution and reliability mechanisms with sample data
## **Week 4**
- Wire the Audit flow in daemon loop
- Test the Audit flow for any issues with existing loop
## **Week 5**
- Write scripts to scan, normalize and fetch gids from IMG-129 results
## **Week 6**
- Process the gids fetched from IMG-129 results
- Write and test scripts to backfill gids from MusicBrainz database
## **Week 7**
- Backfill gids from MusicBrainz database
- Test scripts to scan IA collection to find orphaned items
## **Week 8**
- Scan and fetch all orphaned item gids
## **Week 9**
- Analyze and discuss the entities needing manual review with mentor
## **Week 10**
- Write documentation
- Buffer for any edge cases/issues that might arise
# **Stretch Goals for Remaining week**
As this project could be completed in around 10 weeks, I’ve prepared an extra goal of creating a Dashboard UI to utilize the remaining time.
## **Admin Dashboard UI**
A dashboard to view, filter and perform simple actions on records in the Artwork-Indexer schema making it easy to get a quick look and inspect the tables.
Since this repo uses python, I propose using the Streamlit and Pandas library. It can directly use the existing pg\_conn\_wrapper.py and config.ini to set up database connection, avoiding more infra work and a single [dashboard.py](http://dashboard.py) file will be sufficient to set up everything in a clean way.
[dashboard.py](http://dashboard.py) file will be organised into 3 sections:
- **Config** - reads config.ini and sets up db connection
- **Query helpers** - one function per query to fetch records, each can accept filter parameters
- **Main UI** - the Streamlit layout code
Dashboard will have multiple tabs and each tab will be associated with one Query helper.
For instance, the Failed events tab will use this helper function that can also accept params to display both Release and Event records. Returned rows will be turned into table view using **st.dataframe()**:
```
def get_failed_events(conn):
query = """
SELECT id, entity_type, action, state, last_updated
FROM artwork_indexer.event_queue
WHERE state = 'failed'
AND entity_type = %s
ORDER BY last_updated DESC
"""
result = pd.read_sql(query, conn, params=["release"])
return result
rows = get_failed_events(conn)
st.dataframe(rows)
```
To perform simple actions like changing event status from ‘failed’ to ‘queue’, st.data\_editor() will be used which enables checkboxes on each row to bulk select field values like id. So these can be passed to another helper function like this:
```
def requeue_events(conn, ids):
query = """
UPDATE artwork_indexer.event_queue
SET state = 'queued'
WHERE id = ANY(%s)
"""
with conn.cursor() as cur:
cur.execute(query, [ids])
conn.commit()
result = get_failed_events(conn)
rows = result.copy()
rows.insert(0, "select", False) # insert checkbox column
# making other columns uneditable for safety
edited = st.data_editor(
rows,
disabled=["id", "entity_type", "action", "state", "last_updated"],
hide_index=True,
)
# to get selected row ids and pass them to a helper function using button
selected_ids = edited[edited["select"] == True]["id"].tolist()
if st.button("Re-queue selected"):
if selected_ids:
requeue_events(conn, selected_ids)
st.success(f"Re-queued {len(selected_ids)} events")
st.rerun()
else:
st.warning("No rows selected")
```
Using these methods, many other table views and actions will be enabled on the dashboard UI.
# **Community affinities**
## **What type of music do you listen to?**
I love music that have feel good and fun vibes, recently I’m listening to these songs I discovered from shows and video games:
- Love dramatic - 8ebaff63-ecdf-49fb-a234-b3a9b960958f
- Giri Giri - ac1f8da0-21d7-426e-83b0-befff06f0871
- Ruler of my heart - a2999f63-5a97-4710-a0a3-9b3b25a2eedb
- DamiDami - dcabb48c-a428-4914-a2e7-cc7ad638d641
## **What aspects of MusicBrainz interest you the most?**
The idea of preserving and maintaining information about the artists and their amazing work spanning across decades so they aren’t lost to time really piques my interest.
## **Have you ever used MusicBrainz picard to tag your files or used any of our projects in the past?**
I have not used Picard to tag files yet but while researching this proposal I explored the MusicBrainz database, browsing entries for artists I listen to. This gave me an idea on how the metadata is structured and how inconsistencies in cover art metadata could surface to users.
# **Programming Precedents**
## **When did you first start programming?**
My journey into programming began over a year ago in March 2025 when I picked up C++. I started by solving DSA questions and building crud apps to build a strong foundation. After that I focused more on System Design and Backend concepts.
## **What sort of programming projects have you done on your own time?**
I’ve been building everything from simple, fun Python apps for personal use to Full stack and Backend heavy projects to dive deeper into more complex topics, here are some of the recent ones:
- YouTube Newsletter ( Python app )
- Job Queue System ( Backend Service )
- CitySync - Full stack meetup app with geospatial feed, async workers and s3 uploads
- API Gateway service with API-key based access control
# **Practical Requirements**
## **What computer(s) do you have available?**
I have a Windows 10 desktop pc with specs:
Intel 12th gen i5-12400F
RTX 3060 ti
1TB SSD
32GB RAM
## **How much time do you have available per week, and how do you plan to use it?**
25-30 hours/week, I don’t have any other internships or commitments so I will be fully available for GSoC.
---
### Author:  [@Bitmap](https://community.metabrainz.org/u/Bitmap)
#### Post date: [March 12, 2026, 9:12pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/2 "2026-03-12T21:12:20Z")
Hi @minus_1, thanks for your interest in this project!
> I also engaged with a few open issues related to the database to further deepen that in practice.
> ( MBS-10843, MBS-13254, MBS-13545 )
It’d be nice to see some pull requests from you. From those issues, MBS-13545 should at least be actionable. You can also report your progress on these at our weekly meeting.
> It was mentioned that some initial work was started by bitmap, if possible could you share more details so I can align and refine my approach accordingly?
I cleaned up and pushed the work I had to [GitHub - metabrainz/artwork-indexer at img-129 · GitHub](https://github.com/metabrainz/artwork-indexer/tree/img-129).
1. It’s incomplete.
2. It’s untested.
3. The implementation I started with is not necessarily the best, and doesn’t necessarily mean you should realign your approach. I’d like to hear what you think is best, in your own words. 🙂
4. A lot of your work will be testing/improving this code, and writing scripts to process the auditing data from IMG-129. So your proposal should expand on that. You can also define some stretch goals (for example, an admin UI might be useful).
> Current behaviour of artwork-indexer,
Your understanding sounds correct. 👍
> A periodic audit/reconciliation layer that scans entities, detects inconsistencies and enqueues repair events into artwork\_indexer.event\_queue, reusing the existing core logic.
Would like to hear more about how the scanning will work. Will you insert a new event whenever an entity should be checked, or is that not necessary? What are the new event types you’ll add?
> next\_scan\_after, priority, last\_status, last\_error
Can you explain how each of these fields would be used and why they’re needed? I have an idea for some, but would like to see it explained in the proposal.
> Workers will poll this table for due entities.
Are you proposing to run separate workers for the scanning process, or use the existing event loop?
> Initially snapshot all CAA/EAA entities with artwork, then do incremental upserts from recent changes ( indexer queue events and periodic db checks ).
I don’t understand what this means, can you expand on your idea here?
> Import IDs from IMG-129 audit results and give them higher priority, so most known items are addressed first.
Events are generally processed in the order they’re added. Is there a reason we can’t just insert the high priority events first?
> clean, needs\_repair\_auto, needs\_manual\_check
Would like to hear more about these in your proposal.
- Which of the known issues/inconsistencies can be auto-repaired and which require a manual check?
- Are these statuses stored somewhere?
- If the entity is clean, what updates are you making to the scan table?
> Is it viable to build a new scan table or is there any existing method to build upon?
Yes, it makes perfect sense to track this in a table.
> What will be the constraints around Internet Archive request rates?
The IA doesn’t have any fixed rate limit that I’m aware of, though requests will be denied if they’re over capacity, so that sort of failure should be handled.
P.S. You don’t have to respond individually to all of my comments, but you should ensure your proposal clarifies them. 🙂
---
### Author:  [@minus\_1](https://community.metabrainz.org/u/minus_1)
#### Post date: [March 14, 2026, 7:45am UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/3 "2026-03-14T07:45:41Z")
Thanks for the feedback and sharing that branch! I’m looking into it while also drafting what I think could be the best approach.
Regarding PRs, I didn’t want to open unnecessary PRs so I focused on discussing them first. I’ll go on with MBS-13545 and I also discovered a few issues while exploring artwork-indexer. I’ll move forward with those too.
> Would like to hear more about how the scanning will work. Will you insert a new event whenever an entity should be checked, or is that not necessary? What are the new event types you’ll add?
As most of your questions relate to the new tables and how **cover\_art** and **event\_art** entities will be fed into it. So I’ll explain more on that in detail. I’m still working on it to improve modularity, flow and name schemes. Would love your feedback on it!
For persisting scan results, I’ll use 2 new tables,
> **Audit\_Entity table**
likely fields,
id, entity\_type, gid - which entities exist under audit tracking
status, last\_result - what is the scan result/error status
manual\_review\_needed - whether it needs manual review or not
last\_scan\_at - when it was last scanned
next\_scan\_at - when it needs to be scanned next
> **needs\_manual\_review table**
likely fields,
reason\_type - why an entity needs manual review
reason\_summary - what issue was found
status, resolution\_notes, resolved\_at - what the resolution status is
I’ll explain more clearly on the fields used in both tables.
> **Feeding Audit\_Entity table**
Next is how entities are fed into Audit\_Entity,
Entities enter through 3 feeder paths based on:
- Priority
- Freshness
- Completeness
**Priority ( via IMG-129 )**
Script will be used to fetch, normalize and insert entities from IMG-129 audit results.
> Events are generally processed in the order they’re added. Is there a reason we can’t just insert the high priority events first?
Since that audit result is quite old now, a lot of entities may already be fixed manually or changed/updated over time so they should not be directly inserted into **artwork\_indexer. event\_queue**. Instead they should be first inserted into the Audit module for re-evaluation and to make a fresh decision. For processing order, yes we can insert them first too and use ORDER BY on inserted\_at field just like event\_queue rather than assigning priority.
**Freshness ( via artwork\_indexer.event\_queue )**
A Worker will poll for recently touched entities in **artwork\_indexer.event\_queue** and upsert them into the Audit\_Entity table. Updating the **status** and **next\_scan\_at** so they should be audited earlier than untouched entities.
**Completeness ( via MusicBrainz database )**
A Worker will periodically scan the **MusicBrainz database** to find entities not yet in **Audit\_Entity**. The scan will run in batches and will also maintain a cursor/checkpoint such as last scanned cover\_art id and event\_art id. So the full population can be covered incrementally without repeatedly scanning everything from the start.
> **Inner execution flow of Audit Module**
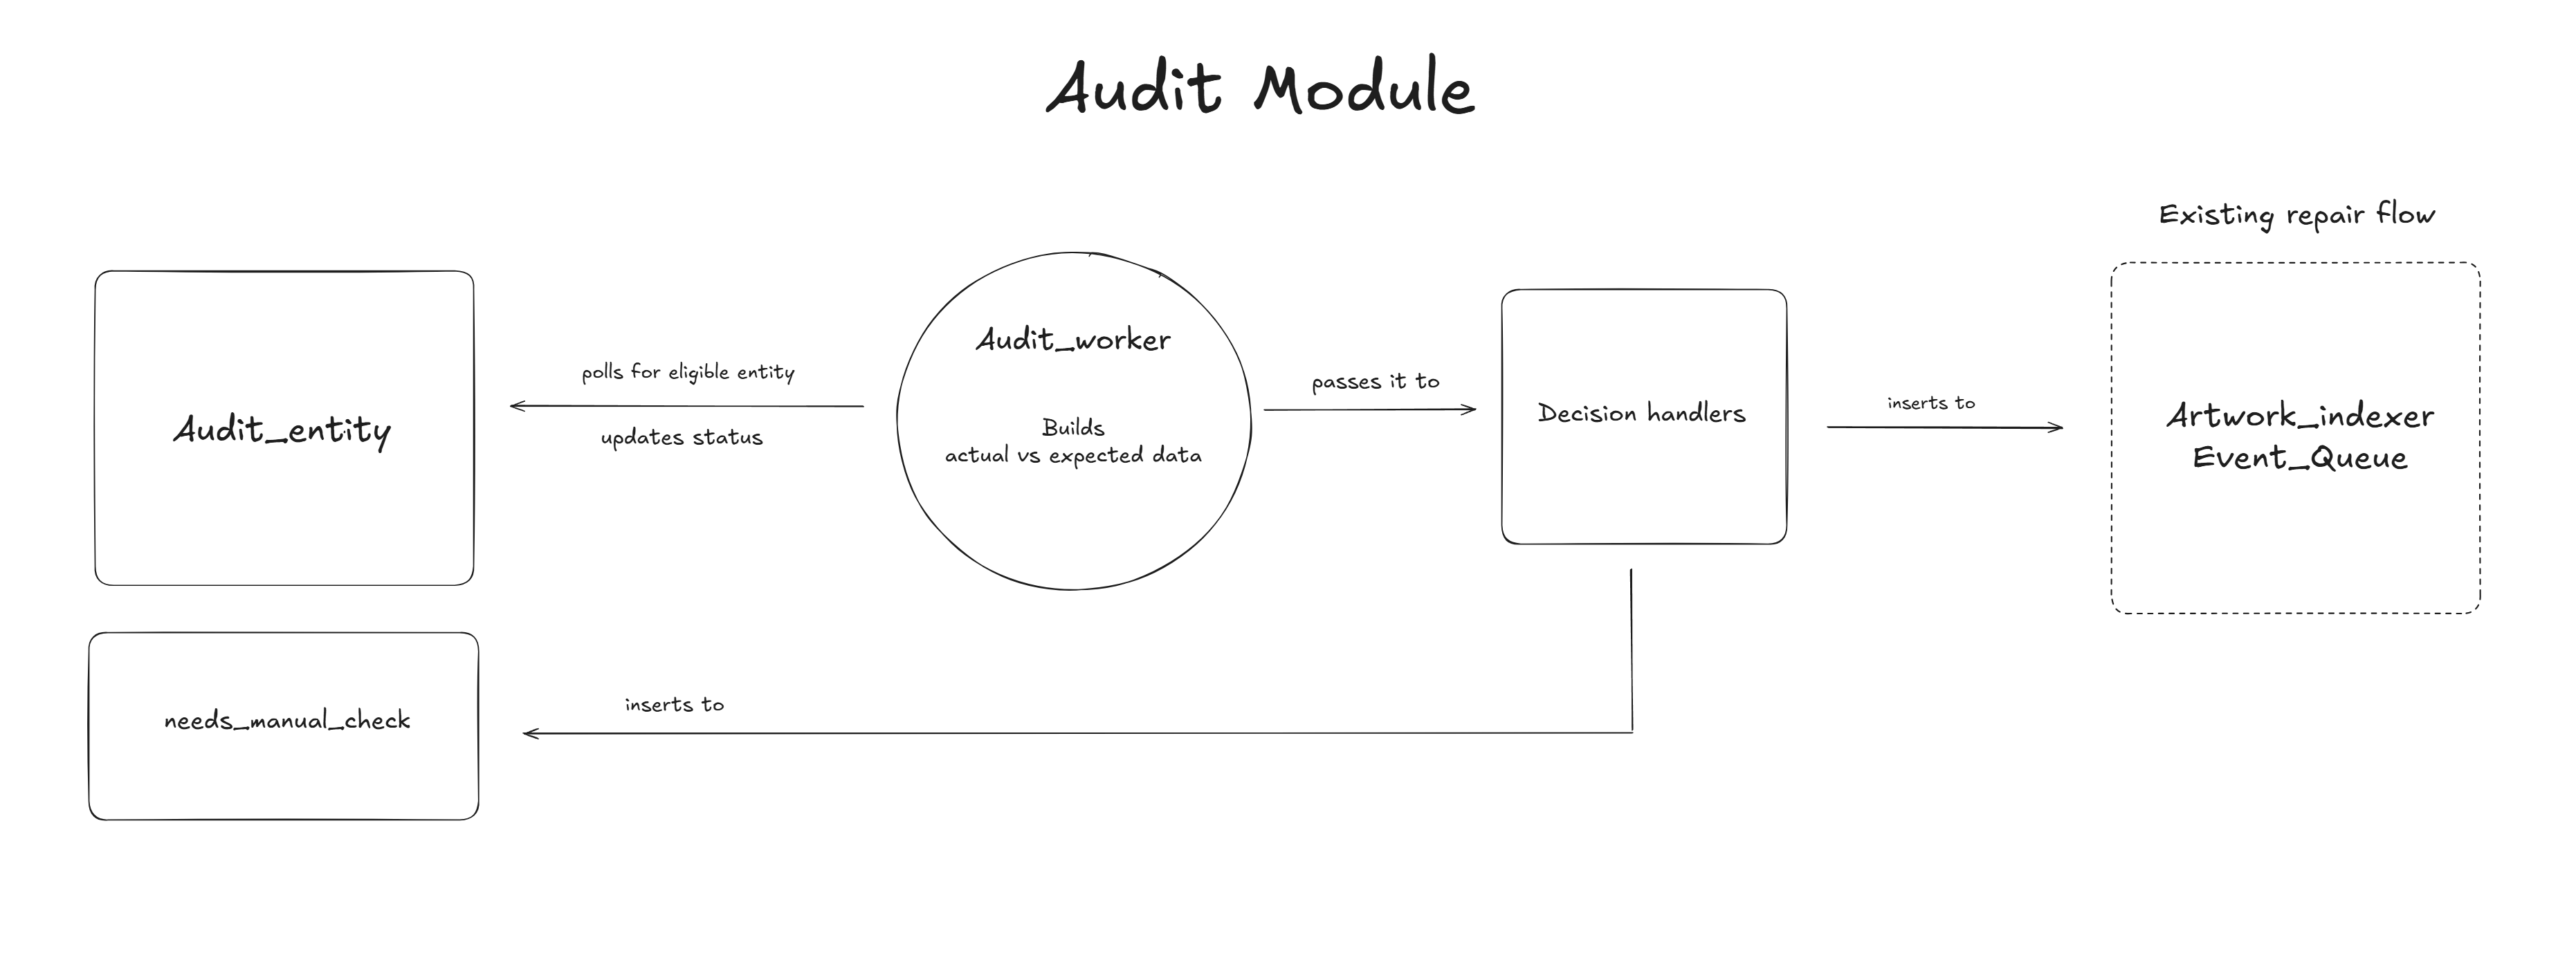
Audit\_Worker will poll for eligible entities from Audit\_Entity based on status fields and last\_scan\_at and next\_scan\_at scheduling fields.
For each selected entity, worker will build the expected and actual state by fetching the relevant index.json and XML data then passing them to the decision handler. Based on the decision returned, worker will update the entity status in Audit\_Entity.
> Would like to hear more about these in your proposal.
>
> - Which of the known issues/inconsistencies can be auto-repaired and which require a manual check?
> - Are these statuses stored somewhere?
> - If the entity is clean, what updates are you making to the scan table?
More details on that,
> **Decision handler**
It will classify each entity into 3 outcomes:
**clean entity**
- no meaningful difference in expected and actual data
- Action - does not require reindex or manual review
**reindex\_needed**
- index.json or, xml expected from MusicBrainz side but missing on IA
- data exists on both but mismatch or malformed
- stale data on IA
- Action - Enqueue repair event in artwork\_indexer.event\_queue
**manual\_review**
- darkened item
- needs IA admin side intervention
- issues not repairable by normal reindexing
- Action - Insert an entry into needs\_manual\_review table
I’ll explain in more detail what data points to use for this classification and decision making process.
Audit\_Worker will update the entity status accordingly based on the decision. For clean entities, it will assign progressively longer intervals based on previous scan results.
I’ll also explain more on why and where the reliability mechanisms are needed such as retry behavior and exponential backoff.
how this Audit module fits into the existing infra,
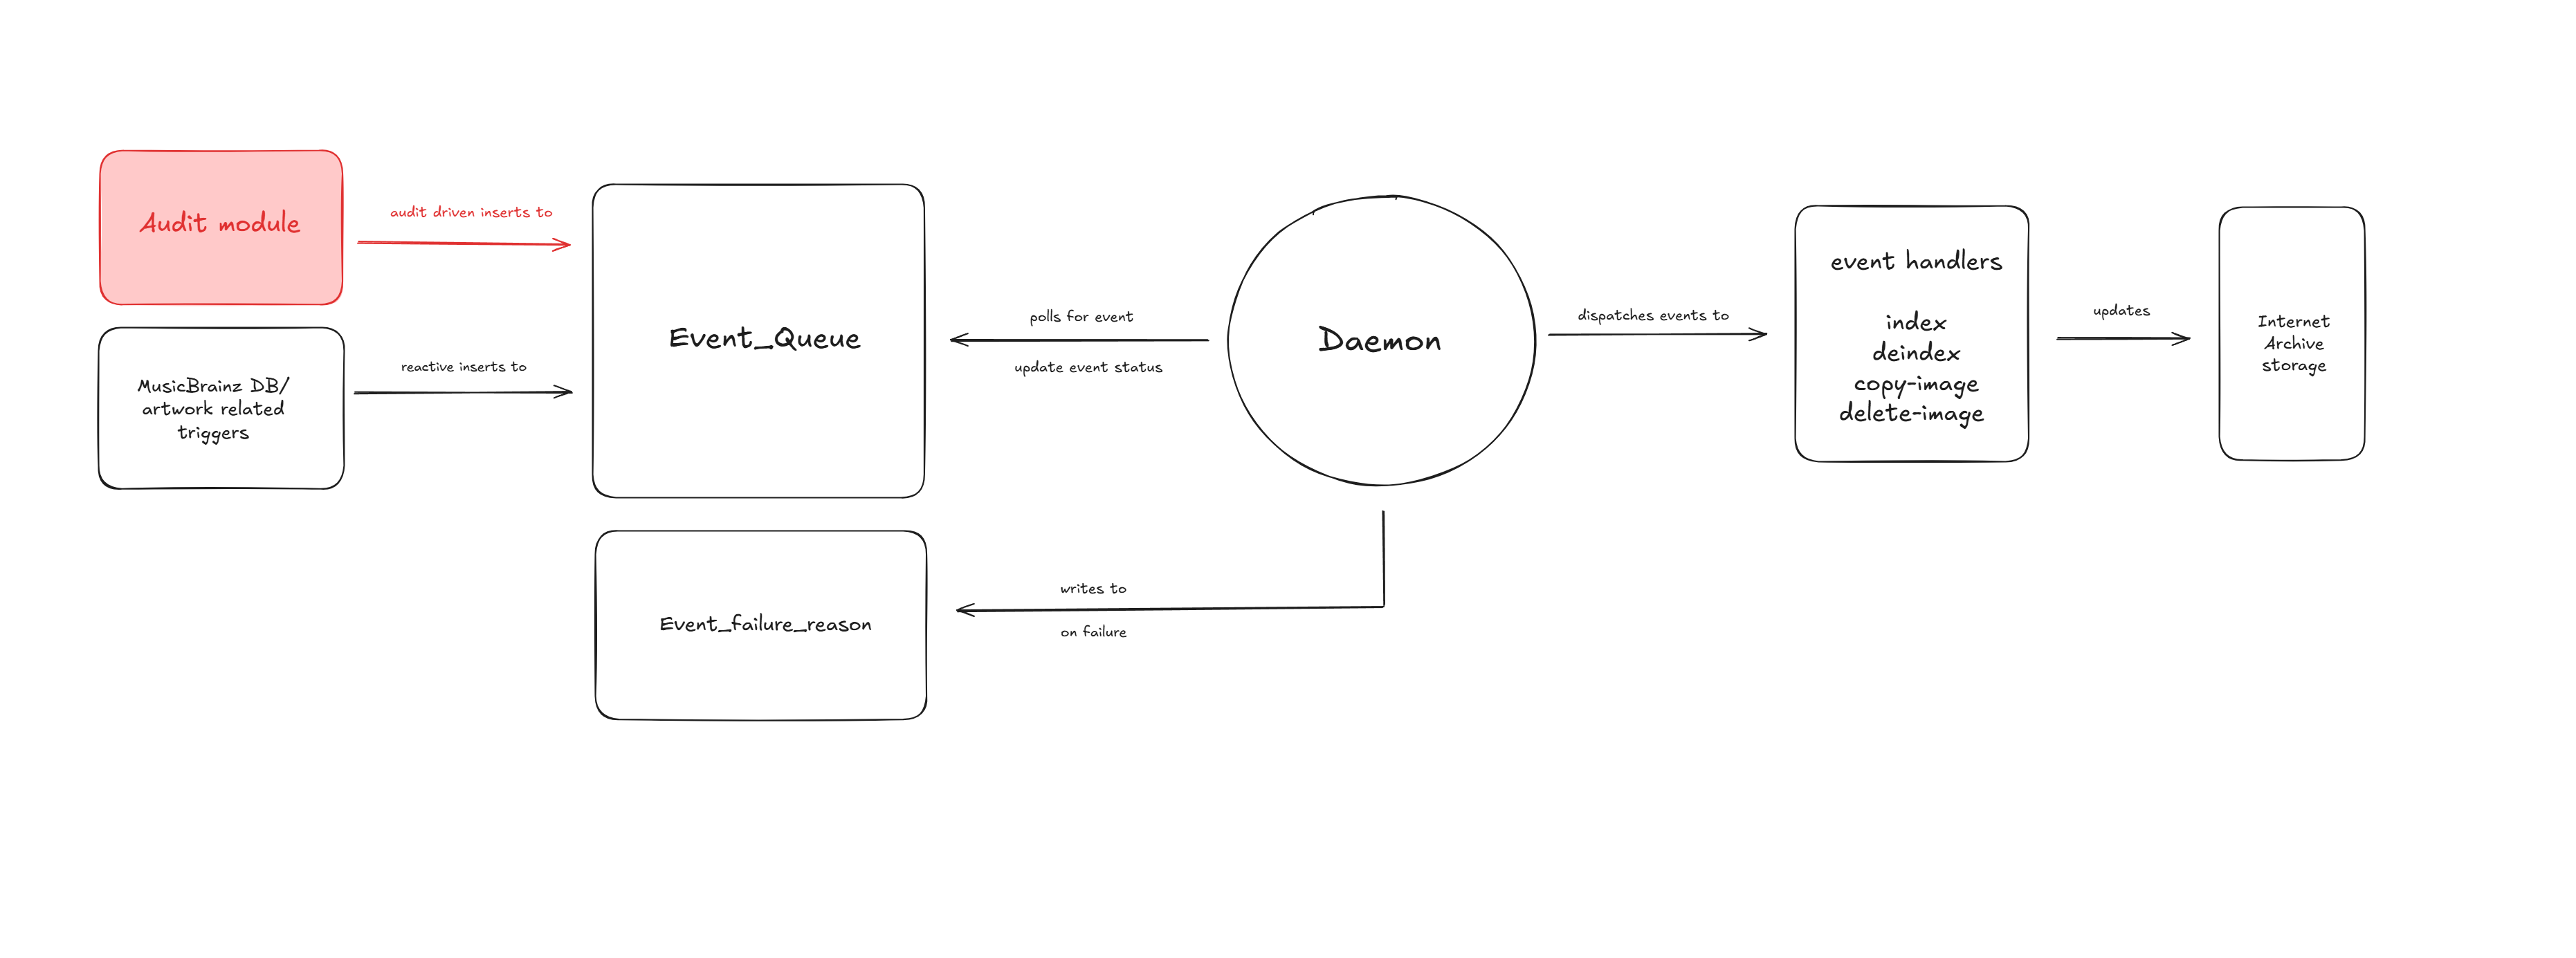
Thanks for reading it through and for your time!
---
### Author:  [@Bitmap](https://community.metabrainz.org/u/Bitmap)
#### Post date: [March 16, 2026, 5:22pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/4 "2026-03-16T17:22:27Z")
Thank you @minus_1 for the additional details. 🙂
> Regarding PRs, I didn’t want to open unnecessary PRs so I focused on discussing them first. I’ll go on with MBS-13545 and I also discovered a few issues while exploring artwork-indexer. I’ll move forward with those too.
That would be great. Just keep in mind we’re unlikely to consider proposals from people who haven’t submitted code before. But there’s still time left in March.
> id, entity\_type, gid - which entities exist under audit tracking
This should work better than the foreign key approach I used, since it allows tracking entities that were removed but still exist in the CAA ([IMG-126](https://tickets.metabrainz.org/browse/IMG-126)).
> status, last\_result - what is the scan result/error status
It’s unclear to me how `last_result` differs from `status`. What kind of result are we storing?
> manual\_review\_needed - whether it needs manual review or not
It seems like this could just be a status indicated by the `status` column.
> last\_scan\_at
The table name uses “audit” but the column names use “scan.” Can we use consistent terminology for these, or is this intentional?
> next\_scan\_at - when it needs to be scanned next
Although you didn’t specify any column types (please do in your proposal), I don’t think this makes sense as a datetime, because we can’t guarantee at what time an item will be scanned. If we’re just using it to order/prioritize things, use a simple smallint priority column.
We should be able to determine what item to audit next based on its `status`, `last_scan_at`, and `priority`. So `next_scan_at` doesn’t seem to be needed, unless I’m missing something.
> Instead they should be first inserted into the Audit module for re-evaluation and to make a fresh decision. For processing order, yes we can insert them first too and use ORDER BY on inserted\_at field just like event\_queue rather than assigning priority.
Thanks, that answers my question. Although based on the above, you will probably want a `priority` column after all.
> A Worker will poll for recently touched entities in artwork\_indexer.event\_queue and upsert them into the Audit\_Entity table. Updating the status and next\_scan\_at so they should be audited earlier than untouched entities.
Are you proposing to do this only for the _initial_ IMG-129 audit results (we do store completed events in `artwork_indexer.event_queue` for 90 days), or to do it continuously as new events come in?
In the latter case, we don’t need a separate worker process to poll for this. That should be avoided. The artwork-indexer already has an event loop where you can access the current event.
I’d also not reprioritize every recently-touched entity, since in some cases they are less likely to have any issues:
1. If the entity was audited recently, there’s no need to prioritize another audit.
2. If the entity itself was recently added (which can be determined from the `musicbrainz.edit` table), there’s no need to prioritize any kind of audit. It should be a low priority to audit these compared to older entities.
> A Worker will periodically scan the MusicBrainz database to find entities not yet in Audit\_Entity. The scan will run in batches and will also maintain a cursor/checkpoint such as last scanned cover\_art id and event\_art id. So the full population can be covered incrementally without repeatedly scanning everything from the start.
This is another case where we don’t need a separate worker. Keep in mind that the artwork-indexer isn’t processing a crazy number of events all the time. We actually run two instances of it on separate hosts, and they are mostly idle waiting for new events to come in. So I’d prefer performing these types of periodic tasks in the existing event loop, when there is no other work to be done. That doesn’t require inserting anything into `event_queue`. See `cleanup_events` for an example of what I’m talking about.
I don’t understand why a cursor is needed here. With a proper index, you can get gids not in the audit table very quickly:
```sql
SELECT gid FROM release WHERE NOT EXISTS (
SELECT 1
FROM audit_entity
WHERE entity_type = 'release'
AND gid = release.gid
);
```
We can even do that for merged/deleted MBIDs (which won’t have anything in the `cover_art` / `event_art` tables anyway).
> For each selected entity, worker will build the expected and actual state by fetching the relevant index.json and XML data then passing them to the decision handler. Based on the decision returned, worker will update the entity status in Audit\_Entity.
You’ll also need to fetch an index of the files that actually exist on [archive.org](http://archive.org), to identify images that still exist but aren’t listed in index.json.
> how this Audit module fits into the existing infra,
It sounds reasonable, but I’d like to avoid a separate Audit\_Worker running in the background: it complicates things for us, and shouldn’t be needed. As I mentioned, the current single-process event loop is mostly idle, and I’d like us to avoid sending even more concurrent requests to the Internet Archive while we’re processing other events, potentially triggering some kind of rate limiting. It makes more sense to me to just run an audit task when there is nothing else to do in the current loop. I haven’t been convinced of this separate worker design. 🙂
If what I’m saying sounds wrong or confusing, it might be faster to discuss this on Matrix.
---
### Author:  [@minus\_1](https://community.metabrainz.org/u/minus_1)
#### Post date: [March 20, 2026, 5:35pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/5 "2026-03-20T17:35:21Z")
@Bitmap Thanks for the feedback and context around daemon workload. I have taken those into account and have put together a first draft of my proposal. I hope you take a look and review it, thanks for giving your time.
I have some doubts regarding the Orphaned items on IA side, do I have to use the search API to scan CAA and EAA collection on IA or is there a database dump available which I can scan through? That will change how I need to approach that part to seed IA side entities into Audit\_Entity.
# **Contact Information**
Name:
Email:
Matrix handle:
LinkedIn:
LeetCode: [https://leetcode.com/u/minus-1/](https://leetcode.com/u/minus-1/)
Github: [MinusOne-01 (minus-1) · GitHub](https://github.com/MinusOne-01)
Mentor: bitmap
Timezone:
Languages: English
# **Introduction**
I am \_\_\_\_ , a programmer with a strong interest in backend systems and database driven development. Over the past several months, I have been building projects that involve designing systems around async processing, background workers and relational database modelling.
One of them is a job queue system that models full job lifecycles (pending, processing, completed, failed, dead) and implements reliability mechanisms such as retry handling and failure recovery logic. Also storing job state and execution history to enable lifecycle tracing and failure diagnostics.
Project repo - [GitHub - MinusOne-01/job-queue-system · GitHub](https://github.com/MinusOne-01/job-queue-system)
The Artwork-Indexer project closely aligns with what I have been learning and building. My projects taught me to think carefully about how background processes behave under failure conditions and how data consistency is maintained over time which is exactly the knowledge needed to understand the current architecture of Artwork-Indexer and extend it with new functionality.
Since deciding to apply, I have been actively exploring the MusicBrainz and Artwork\_Indexer codebase to understand their architecture and schema design. During that I also engaged with the community and mentor to discuss open issues which helped me to contribute through PRs:
- [MBS-13545](https://github.com/metabrainz/musicbrainz-server/pull/3737) - Include cover art related data in Sample dump
- [IMG-163](https://tickets.metabrainz.org/browse/IMG-163) - Reload function ignoring custom config file ( will open PR )
# **Current Architecture of Artwork-Indexer**

Artwork-indexer is a database-driven daemon that processes the repair events from Event\_Queue. These events are generated by PostgreSQL when relevant MusicBrainz/CAA/EAA data changes.
Right now, repair events only get added reactively on new changes so it cannot detect or repair historical drift between MusicBrainz and Internet Archive data.
## Current flow of daemon event loop

1. Polls the event\_queue for any available event to process via get\_next\_event()
2. If event is available, dispatch it to correct handler via run\_event\_handler()
3. If no event is available, periodically run cleanup\_events()
4. Then sleep with backoff and poll again
# **Proposed Project**
Within the existing daemon loop, add a secondary Audit loop that runs on idle time to audit entities and decide whether they can be repaired using the existing repair loop or need manual review.

Initially the number of entities to audit will be really high so to avoid daemon running 24/7 we can add a limit to audit X entities per hour or day as per requirement.
Entity for audit will be selected using FOR UPDATE SKIP LOCKED and status will be changed to ‘audit\_in\_progress’ to avoid other instances claiming the same row.
Updated flow in Idle time when no event is available,
1. periodically run cleanup\_events()
2. run get\_next\_audit() with guardrails/limit
3. if entity available for audit, update status ‘audit\_in\_progress’ and run process\_audit()
4. else sleep with backoff and poll again
# **Schema**
To track which entities are available for audit and persisting there audit results, 2 new tables will be added to the current schema.
# **Audit\_Entity table**
**Structure:**
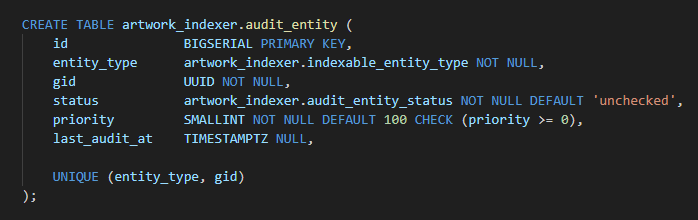
**Use of column(s):**
**entity\_type, gid** will uniquely identify which entities exist under Audit tracking.
**status** will have these states for each entity:
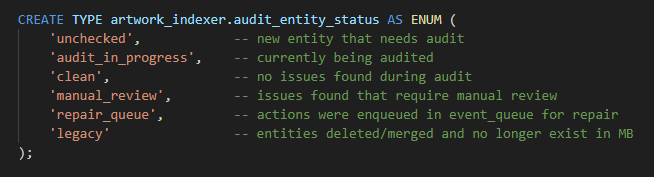
**status, priority, last\_audit\_at** will be used to determine which entity needs to be audited next, example query:
**Indexing:**
**entity\_type, gid** - via UNIQUE constraint
Used for lookups to get entities that does not exist in Audit\_Entity, example:
**priority, last\_audit\_at, id**
Used for getting next entity to audit
# **needs\_manual\_review table**
**Structure:**
**Use of column(s):**
**audit\_entity\_id** - links review record to audited entity in **Audit\_Entity**
**review\_reason** - defines why a manual intervention is needed
**status** will have these states:
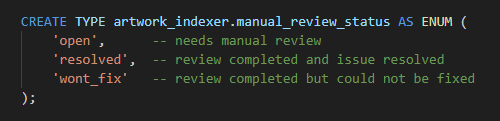
**resolution\_notes** - description for what was actions were taken
**resolved\_at** - timestamp when review was closed
**created\_at** - timestamp when entry was created
**Indexing:**
Partial index on **audit\_entity\_id** to check for open issues
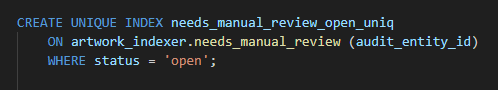
**status, created\_at** for quick issue listing
# **Seeding entities into Audit\_Entity**
## **Fresh data using existing event loop**
The current event loop already reacts to any change in the CAA/EAA database. Upon completion or failure of an event in event\_queue, we can upsert the associated entity into Audit\_Entity (if missing) and update the status accordingly.
That way using the existing loop Audit\_Entity will have the latest status for each entity and any new entity previously not there will be inserted.
## **IMG-129 Audit results**
Auditing data of IMG-129 have well organised results in structured format. A lot of entities in them might not exist in MusicBrainz DB anymore so we can use them to check if any orphaned files still exist on IA.
Since this Audit data is quite old now, it should not be directly inserted into event\_queue. First the available entities need to be fetched, normalized and inserted into the Audit\_Entity table so fresh decisions can be made for those entities.
## **MusicBrainz Database**
Scripts will be used to backfill entities not in Audit\_Entity from the MusicBrainz database.
Example:
## **Orphaned Items from IA**
Script will be used to search the IA CAA and EAA collections and parse gid from each IA item identifier and upsert that gid into Audit\_Entity to get all orphaned/legacy items.
# **Audit process for each entity**
## **1. Build states**
- Expected State
- Build index.json and fetch xml metadata from MusicBrainz
- Actual State
- Fetch index.json and xml metadata from Internet Archive
## **2. Compare states**
Both state files will be compared by:
- does the file exist?
- shape of that file
- compare values in each field
- types of values used like string, int
- ordering of images
## **3. Decision handling**
Depending on comparison results, these decisions could be made with entity status being updated in Audit\_Entity accordingly:
1. **Enqueue for Repair** ( repair\_queue )
- deindex:
- index:
1. **Manual Review** ( manual\_review )
- if IA has images that doesn’t exist on MB anymore, it’s unclear to delete or preserve those images
- If entity fails repeatedly in event\_queue, insert an entry in needs\_manual\_review and update status in Audit\_Entity
1. **Mark as Clean** ( clean )
- No difference in states, simply update the timestamp and status in Audit\_Entity.
# **Timeline**
## **Community bonding period ( May 1 to May 26 )**
- Trace the Artwork-Indexer execution flow end to end, discuss any remaining doubts with mentor
## **Week 1**
- Finalize and implement the structure for Audit\_Entity and needs\_manual\_review table
## **Week 2**
- Draft Implementation details, execution flow, retry and backoff mechanisms for the Audit process
- Function to build index.json and fetch xml files
- Draft decision handler logic to compare states
## **Week 3**
- Test Audit process flow, execution and reliability mechanisms with sample data
## **Week 4**
- Wire the Audit flow in daemon loop
- Test the Audit flow for any issues with existing loop
## **Week 5**
- Write scripts to scan, normalize and fetch gids from IMG-129 results
## **Week 6**
- Process the gids fetched from IMG-129 results
- Write and test scripts to backfill gids from MusicBrainz database
## **Week 7**
- Backfill gids from MusicBrainz database
- Test scripts to scan IA collection to find orphaned items
## **Week 8**
- Scan and fetch all orphaned item gids
## **Week 9**
- Analyze the discuss the entities needing manual review with mentor
## **Week 10**
- Write documentation
- Buffer for any edge cases/issues that might arise
## **Stretch Goals for remaining weeks**
- If all milestones are completed and there’s buffer time
- Admin Review dashboard UI
# **Community affinities**
## **What type of music do you listen to?**
I love music that have feel good and fun vibes, recently I’m listening to these songs I discovered from shows and video games:
Love dramatic - 8ebaff63-ecdf-49fb-a234-b3a9b960958f
Giri Giri - ac1f8da0-21d7-426e-83b0-befff06f0871
Ruler of my heart - a2999f63-5a97-4710-a0a3-9b3b25a2eedb
DamiDami - dcabb48c-a428-4914-a2e7-cc7ad638d641
## **What aspects of MusicBrainz interest you the most?**
The idea of preserving and maintaining information about the artists and their amazing work spanning across decades so they aren’t lost to time really piques my interest.
## **Have you ever used MusicBrainz picard to tag your files or used any of our projects in the past?**
I have not used Picard to tag files yet but while researching this proposal I explored the MusicBrainz database, browsing entries for artists I listen to. This gave me an idea on how the metadata is structured and how inconsistencies in cover art metadata could surface to users.
# **Programming Precedents**
## **When did you first start programming?**
My journey into programming began over a year ago in March 2025 when I picked up C++. I started by solving DSA questions and building crud apps to build a strong foundation. After that I focused more on System Design and Backend concepts.
## **What sort of programming projects have you done on your own time?**
I have been building backend heavy projects for past few months, here are some of the recent ones:
Job Queue System - [GitHub - MinusOne-01/job-queue-system · GitHub](https://github.com/MinusOne-01/job-queue-system)
CitySync - A meetup app with geospatial feed, async workers and s3 uploads - [GitHub - MinusOne-01/citysync\_monorepo · GitHub](https://github.com/MinusOne-01/citysync_monorepo)
API Gateway service with API-key based access control - [GitHub - MinusOne-01/public\_api\_service · GitHub](https://github.com/MinusOne-01/public_api_service)
# **Practical Requirements**
## **What computer(s) do you have available?**
I have a Windows 10 desktop pc with specs:
Intel 12th gen i5-12400F
RTX 3060 ti
1TB SSD
32GB RAM
## **How much time do you have available per week, and how do you plan to use it?**
25-30 hours/week, I don’t have any other internships or commitments so I will be fully available for GSoC.
---
### Author:  [@Bitmap](https://community.metabrainz.org/u/Bitmap)
#### Post date: [March 20, 2026, 9:03pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/6 "2026-03-20T21:03:41Z")
> I have some doubts regarding the Orphaned items on IA side, do I have to use the search API to scan CAA and EAA collection on IA or is there a database dump available which I can scan through? That will change how I need to approach that part to seed IA side entities into Audit\_Entity.
Nope, there used to be a metamgr.php page that admins could fetch items from, but it’s gone. You would indeed have to use the API.
> I am \_\_\_\_ , a programmer
Did you intentionally redact your name, or are you using some kind of template? It’s fine to use your online nickname and not your real name here; only Google would need your real name.
> One of them is a job queue system that models full job lifecycles
Do you have any links to projects you’ve written in Python, preferably without the use of LLMs? Since this is a Python project. 🙂 I haven’t been able to gauge what your Python skills are at all. And I won’t be able to accept a student who I suspect might need to lean on LLMs to finish the project.
Just one bit of feedback on your repository: [v1 done · MinusOne-01/job-queue-system@824908d · GitHub](https://github.com/MinusOne-01/job-queue-system/commit/824908d997366626160154a956b466f952e9eb6b)
These sorts of commits (which combine seemingly unrelated changes with no description or explanation) wouldn’t be acceptable.
> Artwork-indexer is a database-driven daemon that processes the repair events from Event\_Queue. These events are generated by PostgreSQL when relevant MusicBrainz/CAA/EAA data changes.
Small nitpick: in normal cases, I wouldn’t describe them as repair events. That implies something is broken, but it’s normal for there to be some latency before the changes are synced.
> Initially the number of entities to audit will be really high so to avoid daemon running 24/7 we can add a limit to audit X entities per hour or day as per requirement.
Do you think it would be unusual for the artwork-indexer to be running 24/7? (I think you mean having the daemon constantly doing work, but that should generally be fine as long as we aren’t hammering the IA.)
> Audit\_Entity table
I noticed your proposal contains a lot of images of text. Just paste the code (as text) into code blocks.
> needs\_manual\_review table
An “Admin Review dashboard UI” is only briefly mentioned as a stretch goal, so it’s rather unclear and hand-wavy how these manual review features would work. You should either expand on these ideas or remove them if they’re incomplete.
> Enqueue for Repair ( repair\_queue )
> deindex:
> if file on exist on IA but not on MB
We store a few types of files. Are you sure `deindex` is the appropriate action for every type of file?
> index:
> if file exist on MB but not on IA
> if any mismatch between states
What type of file? Are you sure `index` is the appropriate action in every case here?
–
Some general feedback: I appreciate the work you’ve put into this so far, but it’s still hard to tell from the proposal if you have a grasp what the appropriate action is for each type of issue (since there is not much info about it). And that’s going to be a very important part of the project. Inserting all of the entities / audit results into a table won’t do much if it’s unclear how to process them. 🙂
---
### Author:  [@minus\_1](https://community.metabrainz.org/u/minus_1)
#### Post date: [March 26, 2026, 10:19am UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/7 "2026-03-26T10:19:43Z")
> [@Bitmap](#):
>
> Some general feedback: I appreciate the work you’ve put into this so far, but it’s still hard to tell from the proposal if you have a grasp what the appropriate action is for each type of issue (since there is not much info about it). And that’s going to be a very important part of the project. Inserting all of the entities / audit results into a table won’t do much if it’s unclear how to process them. 🙂
Thanks for the feedback, yes I should have put more info in the Audit process part as it’s a core part of this project. I’ve redone the entire section to better reflect my understanding on:
- how files are sent from MB to IA
- which files represents what data
- decision handling to fix out of sync files
There were a couple of things that I couldn’t figure out while looking at the codebase. I’ve shared those doubts below,
Upon deletion of a Release/Event, db triggers delete\_image for all artworks and de index action. But deindex action only removes the index.json file. How are all other files removed?
I noticed that the delete handler sends a http header “x-archive-cascade-delete”, does it mean upon deindex it triggers IA side to delete all entity files?
The same header is also sent with delete\_image, how does it work in that regard?
Here is the new Audit process section,
# **Audit process for each entity**
Currently MusicBrainz uses 2 files to provide necessary information about an Entity (Release/Event) to Internet Archive,
- mb\_metadata.xml
- index.json
## **mb\_metadata.xml**
This file contains all the text based info like:
- title, status, language
- credited artist info - name, sort\_name, country
- release event info
- barcode, asin
- boolean info about cover art availability
- event name, setlist
- supporting artist details
## **index.json**
This file provides the details about all available binaries (artworks) for an Entity.
Currently the Artwork-Indexerer uses **fetch\_image\_rows()** to get all cover\_art rows for an Entity, then **build\_image\_json()** converts the info from that row into an object.
That way, all artwork objects under an Entity are packaged together into a json file that is sent to IA as **index.json**.
These 2 files will be used for the Audit process flow:
- Build States
- Compare
- Decision handling
# **Build states**
## **Expected State**
This is the Source of truth from the MusicBrainz database.
**json file** is already generated by Artwork-Indexer for CAA/EAA so those functions/logic can be reused to build that file.
**xml file** will be fetched from mb web server using these endpoints,
Release - [https://musicbrainz.org/ws/2/release/{mbid}?inc=artists](https://musicbrainz.org/ws/2/release/%7Bmbid%7D?inc=artists)
Event - [https://musicbrainz.org/ws/2/event/{mbid}?inc=artist-rels+place-rels](https://musicbrainz.org/ws/2/event/%7Bmbid%7D?inc=artist-rels+place-rels)
## **Actual State**
Entity files and metadata fetched from the Internet Archive server.
IA provides this endpoint to get metadata of an Entity,
[https://archive.org/metadata/mbid-](https://archive.org/metadata/mbid-)
It includes entity metadata and list all available files for entity like:
- index.json
- mb\_metadata.xml ( metadata from MB side )
- meta.xml ( metadata from IA side )
- original artwork
- derived files such as thumbnails, metadata log
Then mb\_metadata.xml and index.json can be fetched using these endpoints,
[https://archive.org/download/mbid-{mbid}/index.json](https://archive.org/download/mbid-%7Bmbid%7D/index.json)
[https://archive.org/download/mbid-{mbid}/mbid-{mbid}\_mb\_metadata.xml](https://archive.org/download/mbid-%7Bmbid%7D/mbid-%7Bmbid%7D_mb_metadata.xml)
# **Compare**
Both State files will be compared by:
- Does this entity exist on MB DB?
- Does IA have the necessary files?
- Field and values in xml and json file
- Types used by values like string, int
- Ordering of images in index.json
# **Decision Handling**
Multiple checks will run in sequence and a flag method will be used to determine the final decision. So if the manual\_review flag is set at any point then no event\_queue actions will be inserted.
Overview of checks,
## **Entity only exists on IA ( Orphaned entities )**
→ if IA file listing has index.json or main image,
```
Parse artwork-id from filename and check if it exists in cover_art db
if exists
delete_image action as its probably a leftover after merge/update
else
manual_review to check whether it needs to be preserved or purged
deindex if none of the images need manual_review
```
→ any other leftover file like log, xml, thumbnails,
```
manual_review as IA side intervention needed
```
## **Entity exists on MB Database**
→ if mb\_metadata.xml or index.json is missing on IA,
```
index action
```
→ if mb\_metadata.xml on IA has mismatch in fields or values,
```
index action
```
Also the **meta.xml** contains metadata fields like collection, noindex, mediatype. If these are missing or incorrect then **index action** as these fields are sent via the http headers in index handler function.
→ if index.json on IA has extra images then,
```
check if image exists in cover_art db
if exists
delete_image action as its probably a leftover after merge/update
else
manual_review to check whether it needs to be preserved or purged
```
→ if index.json on IA side has:
- incorrect json shape
- missing fields or images
- mismatch in url or field values
- mismatch in types used by fields like string, int
- mismatch in image ordering
> [@Bitmap](#):
>
> An “Admin Review dashboard UI” is only briefly mentioned as a stretch goal, so it’s rather unclear and hand-wavy how these manual review features would work. You should either expand on these ideas or remove them if they’re incomplete.
I’ve redone the stretch goal section, I was not sure how in depth I need to go with it. I’ve added more info while trying to keep it concise, let me know if I need to add more details.
# **Stretch Goals**
As this project could be possible in around 10 weeks, I’ve prepared an extra goal of creating a Dashboard UI to utilize the remaining time.
## **Admin Dashboard UI**
A dashboard to view, filter and perform simple actions on records in the Artwork-Indexer schema making it easy to get a quick look and inspect the tables.
Since this repo uses python, I propose using the Streamlit and Pandas library. It can directly use the existing pg\_conn\_wrapper.py and config.ini to set up database connection, avoiding more infra work and a single dashboard.py file will be sufficient to set up everything in a clean way.
dashboard.py will be organised into 3 sections:
- **Config** - reads config.ini and sets up db connection
- **Query helpers** - one function per query to fetch records, each can accept filter parameters
- **Main UI** - the Streamlit layout code
Dashboard will have multiple tabs and each tab will be associated with one Query helper.
→ For instance, the Failed events tab will use this helper function that can also accept params to display both Release and Event records. Returned rows will be turned into table view using st.dataframe()
```
def get_failed_events(conn, entity_type):
query = """
SELECT id, entity_type, action, state, last_updated
FROM artwork_indexer.event_queue
WHERE state = 'failed'
AND entity_type = %s
ORDER BY last_updated DESC
"""
result = pd.read_sql(query, conn, params=[entity_type])
return result
rows = get_failed_events(conn, "releease")
st.dataframe(rows)
```
→ To perform simple actions like changing event status from ‘failed’ to ‘queue’, st.data\_editor() will be used which enables checkboxes on each row to bulk select field values like id. So these can be passed to another helper function like this:
```
def requeue_events(conn, ids):
query = """
UPDATE artwork_indexer.event_queue
SET state = 'queued'
WHERE id = ANY(%s)
"""
with conn.cursor() as cur:
cur.execute(query, [ids])
conn.commit()
result = get_failed_events(conn)
rows = result.copy()
rows.insert(0, "select", False) # insert checkbox column
# making other columns uneditable for safety
edited = st.data_editor(
rows,
disabled=["id", "entity_type", "action", "state", "last_updated"],
hide_index=True,
)
# to get selected row ids and pass them to a helper function using button
selected_ids = edited[edited["select"] == True]["id"].tolist()
if st.button("Re-queue selected"):
if selected_ids:
requeue_events(conn, selected_ids)
st.success(f"Re-queued {len(selected_ids)} events")
st.rerun()
else:
st.warning("No rows selected")
```
Using these methods, other necessary table views and actions will be enabled on the dashboard UI.
> [@Bitmap](#):
>
> Do you have any links to projects you’ve written in Python, preferably without the use of LLMs? Since this is a Python project. 🙂 I haven’t been able to gauge what your Python skills are at all. And I won’t be able to accept a student who I suspect might need to lean on LLMs to finish the project.
I mainly used Javascript and Typescript while learning System Design and Backend topics as it was more enterprise oriented so I don’t have any python projects related to those.
I’ve been using python for a long while. It’s just that I mostly used it to make basic automation scripts and apps for my daily life convenience. Here is one of them,
[YouTube Newsletter Git repo](https://github.com/MinusOne-01/youtube-newsletter)
> [@Bitmap](#):
>
> Just one bit of feedback on your repository: [v1 done · MinusOne-01/job-queue-system@824908d · GitHub](https://github.com/MinusOne-01/job-queue-system/commit/824908d997366626160154a956b466f952e9eb6b)
> These sorts of commits (which combine seemingly unrelated changes with no description or explanation) wouldn’t be acceptable.
I’ll make sure to follow clean practices for git commit and branches. I made that project a couple of months ago and I’ve improved my commit habits since then.
> [@Bitmap](#):
>
> Small nitpick: in normal cases, I wouldn’t describe them as repair events. That implies something is broken, but it’s normal for there to be some latency before the changes are synced.
Noted!
> [@Bitmap](#):
>
> Do you think it would be unusual for the artwork-indexer to be running 24/7? (I think you mean having the daemon constantly doing work, but that should generally be fine as long as we aren’t hammering the IA.)
Yes I meant that, ill improve the wording for it
“Initially the number of entities to audit will be quite high so in order to not hammer the IA with constant daemon execution, we can add a limit to audit X entities per hour or per day as necessary.”
> [@Bitmap](#):
>
> Did you intentionally redact your name, or are you using some kind of template? It’s fine to use your online nickname and not your real name here; only Google would need your real name.
I’m not using a template, while posting it I just realised its my real name so I did those dashes. Besides that I’m using my real name at all necessary places.
---
### Author:  [@minus\_1](https://community.metabrainz.org/u/minus_1)
#### Post date: [March 30, 2026, 3:02pm UTC](https://community.metabrainz.org/t/gsoc-2026-daemon-that-corrects-out-of-sync-cover-art-and-event-art-metadata-on-archive-org/814396/8 "2026-03-30T15:02:12Z")
I have updated the main post with the all the changes to reflect the updated proposal.